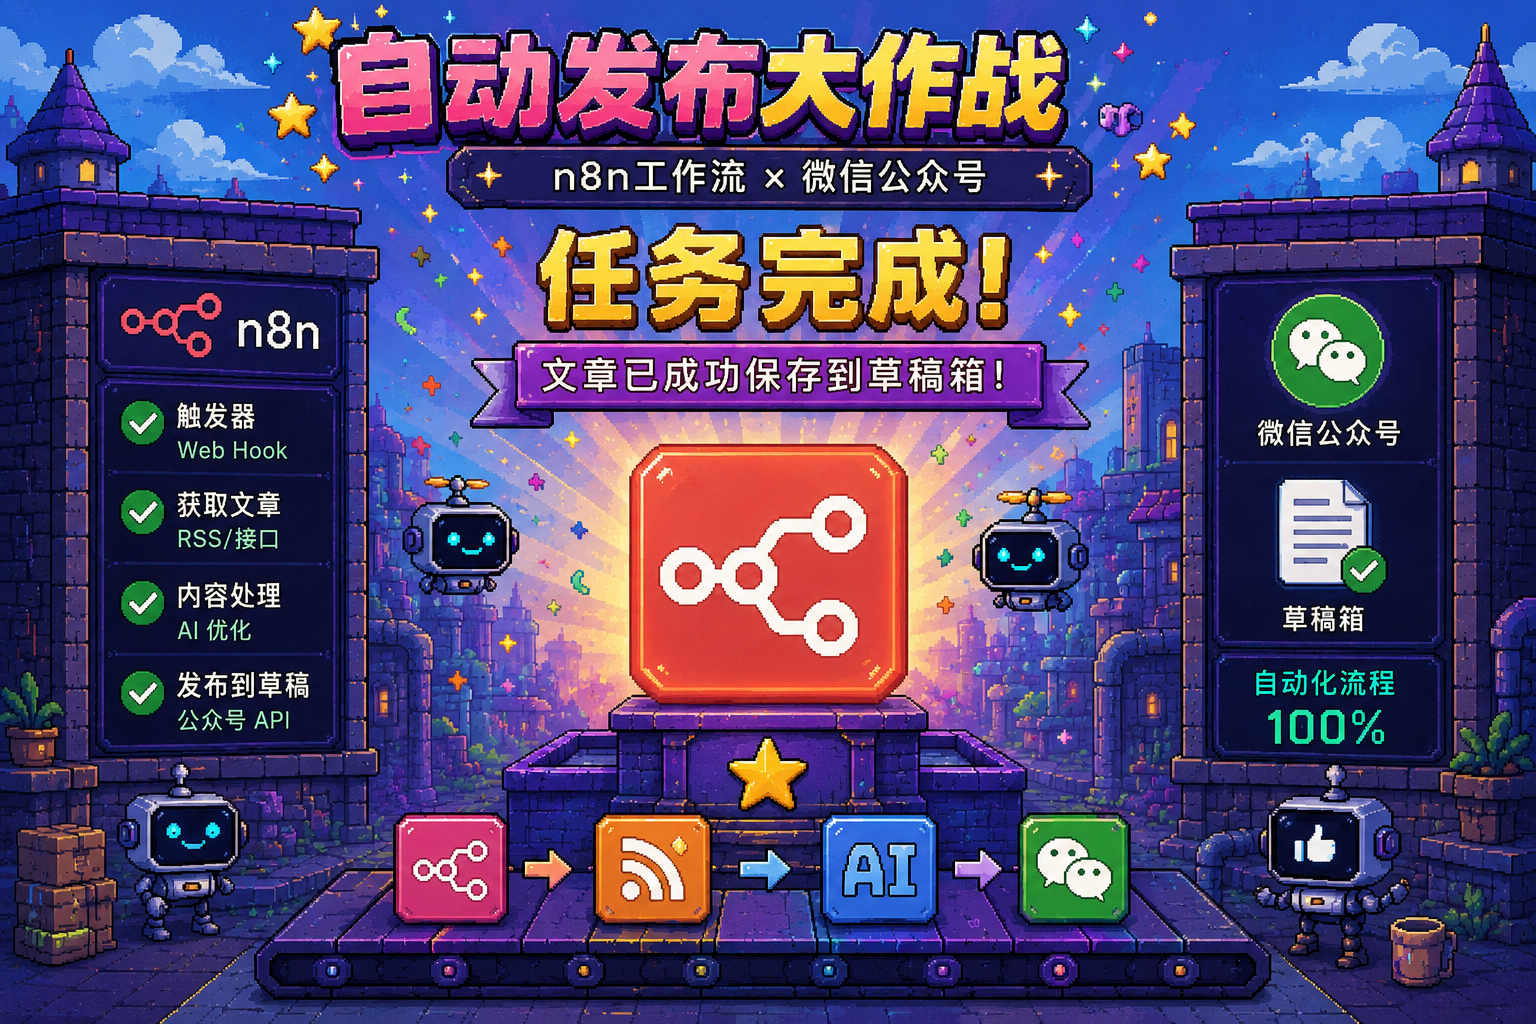


运营一个微信公众号,真正消耗时间的往往不是最后点击“发布”,而是发布之前的一系列准备工作。每天需要寻找新闻、筛选选题、整理资料、撰写正文、设计封面、调整排版,再把文章和图片上传到微信公众号后台。偶尔发布一篇并不困难,但如果要保持稳定日更,或者同时运营多个账号,人工成本就会迅速增加。
为了解决这些重复工作,我们基于 n8n 搭建了一套完整的微信公众号内容自动化系统。它不是单独调用一次 GPT 生成文章,而是把新闻采集、选题筛选、文章生产、封面生成、公众号排版和草稿上传连接成一条可以定时运行的自动化流水线。
完整流程:联网采集 AI 新闻 → 筛选优质选题 → AI 生成公众号长文 → 自动生成封面 → 自动整理公众号格式 → 上传微信公众号草稿箱。
项目参考入口:n8n 官方项目;大模型接口可使用 Token API;也可以查看已经生成的微信公众号成品文章。
一套完整的公众号内容生产流水线
这套系统由多个独立的 n8n 工作流组成,分别负责新闻摘要、文章生产、封面生成、格式检查和微信草稿上传。不同工作流通过 Data Table 传递数据,并用状态字段记录每篇文章当前进行到哪一步。
这样设计的好处是,即使其中一个步骤暂时失败,也不需要将整条流程从头再跑。例如文章已经生成成功,但图片接口临时超时,那么重新运行生图工作流即可,不会再次采集新闻或重复生成正文。
系统同时支持定时执行和手动触发。日常运行可以完全交给定时任务;遇到热点新闻、临时补充内容或者需要测试某个节点时,也可以进入 n8n 手动启动对应工作流。
第一步:联网采集当天最新 AI 新闻
每天早上,新闻摘要工作流会自动启动 AI 新闻智能体。当前配置保留“每日 07:30”和“手动触发”两个入口,运营者可以根据自己的发布时间修改定时节点,保存并重新 Publish 后即可生效。
AI 新闻智能体通过联网搜索获取当天最新资讯,重点关注大模型、多模态、AI Agent、MCP、AI 编程工具、前端与设计工具、推理部署、训练框架、芯片算力、重要研究论文、模型安全以及行业监管等内容。OpenAI、Anthropic、Google DeepMind、Meta AI 等核心机构的官方信息会被优先考虑。
为了减少低质量内容,提示词会主动降低或排除纯营销信息、重复搬运、普通入门教程、金融行情、政治新闻和与 AI 关系不大的综合资讯。每次任务按照固定格式整理 25 条候选新闻,每条内容都包含标题、真实来源链接、事实摘要、推荐评分和标签。
这里追求的不是采集数量越多越好,而是先建立一个经过筛选、格式统一的选题池,为后续文章生成提供稳定素材。
第二步:将新闻摘要写入 Data Table
新闻采集完成后,结果不会直接进入文章生成节点,而是先写入名为 horizon_summaries 的 Data Table。每次执行会记录执行编号、状态、摘要日期、摘要名称、完整 Markdown 内容和错误信息。
只有状态为 succeeded 的成功记录,才会被文章生产工作流读取。这相当于在新闻采集和文章生成之间增加了一个可靠的数据缓冲层。即使后续工作流稍晚运行,或者 n8n 中途重启,已经采集成功的内容也不会丢失。
工作流名称虽然仍保留“摘要控制台”,但当前项目已经不再依赖单独的 Horizon 服务。联网搜索、内容整理和摘要保存都由 n8n 内部的 AI 工作流完成,部署结构更加简单,也减少了两个服务之间互相调用和等待的故障点。
第三步:从 25 条新闻中选择文章主题
文章生产工作流会读取最新一条成功摘要,并按照固定结构解析其中的 25 条新闻。系统会检查每条内容是否拥有完整标题、真实链接和足够长度的事实摘要。内容过短、结构不完整或者无法解析的记录不会进入文章生成阶段。
当前配置会从符合条件的候选新闻中随机选择两条,用于当天的公众号文章生产。采用随机选择可以降低每天主题重复的概率,也能让不同方向的 AI 新闻获得曝光机会。后续还可以继续增加评分排序、关键词权重、品牌过滤或者人工确认节点。
第四步:AI 自动生成完整公众号文章
选题确定后,系统会调用兼容 OpenAI 接口的大模型,将新闻摘要扩展成适合微信公众号阅读的完整文章。它不是简单复制原新闻,而是根据事实重新组织标题、背景、核心变化、技术价值和行业影响。
- 提炼一个适合公众号传播的主标题,并控制标题长度。
- 补充必要的事件背景和技术知识,帮助普通读者理解。
- 为正文建立清晰的小标题和完整段落。
- 说明产品、模型或平台发生了什么具体变化。
- 分析新能力对开发者、企业和行业的实际意义。
- 删除采集内容中的原始链接、地址和无关提示语。
- 把正文控制在约 1500 至 2500 字,适配移动端阅读。
提示词要求文章使用自然、通俗的中文表达,减少生硬的新闻播报感,同时避免把一句话拆成很多零散小段。生成结果会保留主标题、小标题和段落间距,方便后续统一转换成公众号 HTML。
第五步:用状态字段管理每篇文章
文章生成完成后,会写入名为 content_articles 的 Data Table。系统为每篇文章生成唯一的 article_key,并保存标题、正文、来源执行编号、摘要日期、封面路径、微信草稿编号和错误信息。
article_status:记录文章是否已经准备完成。image_status:记录封面是等待生成、处理失败还是已经完成。wechat_status:记录文章是等待推送还是已经进入草稿箱。
文章写入使用 Upsert 逻辑。相同任务再次运行时,系统会根据唯一标识更新已有记录,尽量避免创建重复文章。运营者也可以直接打开 Data Table,查看每篇文章当前进行到了哪一步。
第六步:根据文章内容自动生成封面图
生图工作流只读取文章状态为 ready、图片状态为 pending 的记录。系统会从标题和正文中提取主题、品牌、产品名称和技术关键词,再交给图片生成接口制作封面。
当前封面采用高清像素插画方向,强调鲜明主体、事件场景、品牌元素和新闻感。提示词会要求图片围绕标题建立明确的视觉故事,而不是只生成一张没有主题的蓝紫色科技背景。
例如文章涉及 ChatGPT、Claude、Gemini、DeepSeek、GitHub、n8n、Cloudflare 或 Supabase 时,系统会尝试将对应产品、界面、设备、代码窗口、数据中心或芯片场景融入画面。图片生成成功后会保存到指定目录,并将路径写回 Data Table,同时把图片状态更新为 ready。
第七步:自动整理微信公众号排版
大模型生成的内容通常是 Markdown,但微信公众号草稿接口需要可以直接显示的 HTML。因此,在上传之前,工作流会进行一次专门的格式转换、内容清理和结构检查。
- 去掉正文第一行中重复出现的文章标题。
- 识别正文小标题并设置加粗、字号和上下间距。
- 合并过短、过碎的段落,保持阅读连贯性。
- 转换项目列表、重点文字和代码内容。
- 删除“排版提示”“配图建议”等不应该出现在成品正文中的内容。
- 将正文统一为适合手机阅读的 16px 字号和舒适行高。
- 检查正文是否为空、是否缺少小标题以及样式是否完整。
- 根据需要在文章结尾加入指定尾图或推广入口。
完成这一步后,文章已经具备较为完整的移动端排版。进入公众号草稿箱后,运营者只需要进行最终检查,不必再从空白页面重新整理格式。
第八步:上传封面并创建微信公众号草稿
微信公众号草稿上传分为两个关键动作。首先,系统读取本地生成的封面文件,通过微信公众号素材接口上传图片,并取得对应的 media_id。随后,工作流将标题、HTML 正文、摘要、封面素材编号和其他必要字段组合成微信草稿数据,再调用草稿接口创建文章。
创建成功后,微信接口会返回草稿媒体编号。系统会把编号写回 content_articles,并将文章状态更新为 drafted。至此,文章就已经自动进入微信公众号后台的草稿箱。
需要注意:当前系统默认完成的是自动上传草稿,而不是绕过审核直接群发。运营者仍然应该在公众号后台检查新闻事实、标题、封面和排版,确认无误后再正式发布。
默认自动运行时间
当前项目按照北京时间组织整条工作流。以下是默认执行顺序,所有时间都可以在 n8n 的 Schedule Trigger 节点中调整:
- 07:30:新闻摘要控制台联网采集并整理当天 AI 新闻。
- 08:30:生产文章工作流选择新闻并生成公众号长文。
- 10:00:生图工作流为待处理文章生成封面。
- 10:20:微信工作流上传封面并创建公众号草稿。
- 每 6 小时:格式稳定性自检工作流检查字号、小标题和排版残留。
每个核心工作流也保留手动触发入口,因此测试接口、处理突发新闻或者重新生成某一步时,不需要等待下一次定时任务。
为什么要拆成多个独立工作流
把采集、写作、生图和微信上传全部放进一个巨大工作流,看起来更直观,但实际维护并不方便。任何一个外部接口超时,都可能导致整条任务失败;重新运行时还可能再次采集新闻、重复生成文章或重复上传草稿。
拆分以后,每个工作流只处理满足指定状态的数据:新闻采集负责建立候选池,文章工作流负责把摘要转换成正文,生图工作流只处理缺少封面的文章,微信工作流只处理文章和图片都准备完成的记录,自检工作流则专门发现排版异常。
这种结构更加适合长期稳定运行,也方便以后继续接入 WordPress、X、Telegram 或其他内容平台。
Docker 私有化部署,数据由自己掌握
整个项目使用 Docker Compose 部署在自己的 Linux 服务器上。文章、图片、工作流、执行记录和 Data Table 都保存在自己的 n8n 环境中。与功能固定的在线 SaaS 相比,私有化部署允许用户自由修改节点、提示词、模型接口、定时规则和数据结构。
首次部署通常需要准备 Linux 服务器、Docker Engine、Docker Compose、可用的大模型 API、图片生成接口、已认证的微信公众号、公众号 AppID 与 AppSecret,以及正确配置的服务器 IP 白名单。
项目还包含自定义图片节点和微信公众号社区节点,启动时会自动加载相关扩展。由于部署快照可能包含工作流配置和凭证信息,保存完整环境的 Git 仓库必须保持私有,不能直接公开。
自动化不等于完全放弃人工审核
AI 可以显著减少重复劳动,但内容平台仍然需要人工把关。新闻可能出现后续变化,AI 生成的标题也可能过于夸张;图片模型在生成中文、品牌 Logo 和产品界面时,也可能出现错字或视觉细节错误。
- 新闻来源、时间、数字和产品名称是否准确。
- 标题是否存在误导、夸张或者事实偏差。
- 正文是否包含不确定信息或过时结论。
- 封面文字、品牌元素和产品图标是否正确。
- 文章是否符合微信公众号的平台规则。
- 文末链接和推广内容是否仍然有效。
系统负责把几个小时的重复劳动压缩成一次最终审核,而不是替代运营者对内容质量承担责任。
这套系统适合哪些用户
AI 与科技类公众号
每天自动追踪模型发布、开源项目、开发工具和行业动态,减少人工搜索和整理资料的时间。
自媒体矩阵运营者
将同一套内容生产能力扩展到多个账号,并根据不同账号定位配置关键词、文章语气和封面风格。
企业品牌账号
持续输出行业资讯、产品解读和技术内容,建立更加稳定的品牌曝光。
内容工作室
为不同客户部署独立工作流,并根据行业修改新闻来源、提示词、封面风格和发布平台。
个人开发者与独立创业者
不需要组建完整的编辑和设计团队,也能建立一套可以持续运行的内容生产系统。
可提供的部署与定制服务
对于不熟悉 Docker、n8n、AI 接口或微信公众号 API 的用户,可以提供 n8n 私有化部署、成品工作流安装、大模型接口配置、新闻来源与关键词定制、写作提示词优化、封面风格定制、微信公众号接口对接、草稿上传调试、运行错误排查,以及 WordPress、X、Telegram 等平台扩展。
每个账号的定位不同,适合的选题、语气、文章长度和图片风格也不一样。工作流可以根据科技、商业、电商、游戏、教育或企业品牌等方向进行针对性调整。如需沟通和定制开发,可以通过网站页脚联系方式联系站长。
让 AI 成为内容团队的自动化助手
这套系统真正解决的,不只是“让 GPT 写一篇文章”,而是把内容生产中大量重复、机械、容易出错的步骤连接起来。从每天早上的新闻采集,到选题筛选、文章生成、封面制作、格式整理,再到进入微信公众号草稿箱,整个过程都可以按照预定时间自动完成。
运营者不再需要每天从空白页面开始工作,只需要在系统已经准备好的草稿基础上进行审核、修改和发布。当内容生产从一次次人工操作变成一条稳定运行的工作流,AI 才真正从一个聊天工具,变成能够长期参与业务的内容助手。
附录:6 个 n8n 工作流与 Data Table Schema
下面代码来自当前 n8n 实例中已经发布的工作流版本。为避免泄露或错误复用,凭证 ID、Data Table ID、项目 ID 和运行数据均已移除或替换为 REPLACE_WITH_* 占位符。
使用方法:将每个工作流代码分别保存成独立的 .json 文件,再通过 n8n 的 Import from File 导入。导入后先创建 Data Table、重新选择凭证和数据表,并确认自定义节点已经安装;全部检查完成前不要启用定时任务。
依赖节点包括微信公众号社区节点 n8n-nodes-wechat-offiaccount 和项目自定义节点 CUSTOM.imageRelay。缺少这些节点时,相关工作流可以导入,但不能正常执行。
工作流 1:AI 新闻摘要(联网搜索)(点击展开代码)
{
  "name": "Horizon 摘要控制台",
  "nodes": [
    {
      "parameters": {},
      "id": "manual-trigger-ai-news",
      "name": "手动触发",
      "type": "n8n-nodes-base.manualTrigger",
      "typeVersion": 1,
      "position": [
        240,
        288
      ]
    },
    {
      "parameters": {
        "rule": {
          "interval": [
            {
              "triggerAtHour": 7,
              "triggerAtMinute": 30
            }
          ]
        }
      },
      "id": "schedule-trigger-ai-news",
      "name": "每日 07:30",
      "type": "n8n-nodes-base.scheduleTrigger",
      "typeVersion": 1.3,
      "position": [
        240,
        448
      ]
    },
    {
      "parameters": {
        "modelId": {
          "__rl": true,
          "mode": "id",
          "value": "gpt-5.6-terra"
        },
        "responses": {
          "values": [
            {
              "content": "={{ '请使用联网搜索,整理北京时间今天(' + $now.setZone('Asia/Shanghai').toFormat('yyyy-MM-dd') + ')最新且有事实来源的 AI 新闻。严格筛选并只输出 25 条:\\n\\n1. 大模型、多模态、Agent、MCP 的新模型、新能力、重大版本发布与开源进展;\\n2. AI 开发工具、前端技术与设计项目、推理部署、训练框架、算力基础设施和高价值工程实践;\\n3. 重要 AI 研究论文、基准评测、模型安全、监管以及会影响行业的关键动态;\\n4. OpenAI、Anthropic、Google DeepMind、Meta AI 等核心机构的重要官方信息;\\n5. 具有实质讨论价值的 AI 社区热点。\\n\\n降低或排除:纯营销、重复搬运、低价值入门教程、普通非 AI 项目、金融行情、政治及社会综合新闻。\\n\\n输出要求:只输出 Markdown 正文,不要标题前言、总结、解释或代码围栏;每条一行,格式为“1. [新闻标题](真实来源 URL)”;必须正好 25 条、标题不得重复、链接必须是搜索结果中的真实可访问 URL;优先使用官方公告、论文原文、项目仓库或高质量原报道。' }}"
            }
          ]
        },
        "builtInTools": {
          "webSearch": {
            "searchContextSize": "medium"
          }
        },
        "options": {
          "maxTokens": 3500,
          "store": false
        }
      },
      "id": "openai-ai-news-agent",
      "name": "AI 新闻智能体(联网搜索)",
      "type": "@n8n/n8n-nodes-langchain.openAi",
      "typeVersion": 2.3,
      "position": [
        560,
        368
      ],
      "retryOnFail": true,
      "maxTries": 2,
      "waitBetweenTries": 5000,
      "credentials": {
        "openAiApi": {
          "id": "REPLACE_WITH_OPENAIAPI_CREDENTIAL_ID",
          "name": "请在 n8n 中重新选择对应凭证"
        }
      }
    },
    {
      "parameters": {
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_HORIZON_SUMMARIES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "horizon_summaries"
        },
        "columns": {
          "mappingMode": "defineBelow",
          "value": {
            "run_id": "={{ $execution.id }}",
            "status": "succeeded",
            "summary_date": "={{ $now.setZone('Asia/Shanghai').toFormat('yyyy-MM-dd') }}",
            "summary_file_name": "={{ 'ai-news-' + $now.setZone('Asia/Shanghai').toFormat('yyyy-MM-dd') + '.md' }}",
            "summary_markdown": "={{ $json.output?.find(item => item.type === 'message')?.content?.find(item => item.type === 'output_text')?.text || '' }}"
          },
          "matchingColumns": [],
          "schema": [
            {
              "id": "run_id",
              "displayName": "run_id",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "status",
              "displayName": "status",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "summary_date",
              "displayName": "summary_date",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "summary_file_name",
              "displayName": "summary_file_name",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "summary_markdown",
              "displayName": "summary_markdown",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "error",
              "displayName": "error",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            }
          ],
          "attemptToConvertTypes": false,
          "convertFieldsToString": false
        },
        "options": {}
      },
      "id": "save-ai-news-to-table",
      "name": "保存 AI 新闻摘要到 Data Table",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        880,
        368
      ]
    }
  ],
  "connections": {
    "手动触发": {
      "main": [
        [
          {
            "node": "AI 新闻智能体(联网搜索)",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "每日 07:30": {
      "main": [
        [
          {
            "node": "AI 新闻智能体(联网搜索)",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "AI 新闻智能体(联网搜索)": {
      "main": [
        [
          {
            "node": "保存 AI 新闻摘要到 Data Table",
            "type": "main",
            "index": 0
          }
        ]
      ]
    }
  },
  "settings": {
    "executionOrder": "v1",
    "callerPolicy": "workflowsFromSameOwner",
    "binaryMode": "separate"
  },
  "active": false,
  "pinData": {},
  "tags": []
}
工作流 2:生产公众号文章(点击展开代码)
{
  "name": "生产文章",
  "nodes": [
    {
      "parameters": {
        "options": {}
      },
      "type": "n8n-nodes-base.splitInBatches",
      "typeVersion": 3,
      "position": [
        800,
        -352
      ],
      "id": "fe089cfb-4a44-4e21-b00c-57577bb1d192",
      "name": "Loop Over Items"
    },
    {
      "parameters": {
        "rule": {
          "interval": [
            {
              "triggerAtHour": 8,
              "triggerAtMinute": 30
            }
          ]
        }
      },
      "id": "7c1a7dc7-9008-44ed-b27b-9a6c6f69ab71",
      "name": "Schedule Trigger1",
      "type": "n8n-nodes-base.scheduleTrigger",
      "typeVersion": 1.2,
      "position": [
        304,
        -480
      ]
    },
    {
      "parameters": {
        "operation": "get",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_HORIZON_SUMMARIES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "horizon_summaries"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "status",
              "keyValue": "succeeded"
            }
          ]
        },
        "limit": 1,
        "orderBy": true
      },
      "id": "d6829130-c011-400a-8a5c-dedac28b303f",
      "name": "读取Horizon摘要1",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        480,
        -480
      ],
      "alwaysOutputData": true
    },
    {
      "parameters": {
        "jsCode": "const row = $input.first().json ?? {};\nconst text = typeof row.summary_markdown === 'string'\n  ? row.summary_markdown.trim()\n  : '';\nconst sourceFile = row.summary_file_name || '';\nconst sourceRunId = row.run_id || '';\nconst summaryDate = row.summary_date || '';\n\nif (!text) {\n  throw new Error(\n    'No successful Horizon summary was found in Data Table horizon_summaries'\n  );\n}\n\nconst lines = text.split('\\n');\nconst sections = [];\nlet current = null;\n\nfor (const line of lines) {\n  if (/^## /.test(line)) {\n    if (current) sections.push(current);\n    current = {\n      title: line.replace(/^## /, '').trim(),\n      content: [],\n    };\n  } else if (current) {\n    current.content.push(line);\n  }\n}\nif (current) sections.push(current);\n\nconst items = sections\n  .map((section) => ({\n    title: section.title,\n    content: section.content.join('\\n').trim(),\n  }))\n  .filter((section) => section.content.length > 100)\n  .map((section) => ({\n    json: {\n      title: section.title,\n      content: section.content,\n      url: '',\n      score: 8,\n      source: 'Horizon',\n      sourceFile,\n      sourceRunId,\n      summaryDate,\n    },\n  }));\n\nif (items.length === 0) {\n  throw new Error(\n    'No usable sections found in Horizon Data Table summary: ' +\n      (sourceRunId || sourceFile || 'unknown row')\n  );\n}\n\nfor (let index = items.length - 1; index > 0; index--) {\n  const randomIndex = Math.floor(Math.random() * (index + 1));\n  [items[index], items[randomIndex]] = [items[randomIndex], items[index]];\n}\n\nreturn items.slice(0, 2);"
      },
      "id": "6b809a6e-652a-4c98-89e3-9af41069816f",
      "name": "解析Horizon1",
      "type": "n8n-nodes-base.code",
      "typeVersion": 2,
      "position": [
        624,
        -480
      ]
    },
    {
      "parameters": {
        "method": "POST",
        "url": "https://token.macosabc.com/v1/chat/completions",
        "authentication": "predefinedCredentialType",
        "nodeCredentialType": "openAiApi",
        "sendHeaders": true,
        "headerParameters": {
          "parameters": [
            {
              "name": "User-Agent",
              "value": "Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/127.0 Safari/537.36"
            },
            {
              "name": "Accept",
              "value": "application/json"
            }
          ]
        },
        "sendBody": true,
        "specifyBody": "json",
        "jsonBody": "={{ { model: 'gpt-5.6-luna', messages: [ { role: 'system', content: \"将以下新闻内容扩展改写为一篇完整的公众号文章:\\n\\n- 首行是文章标题(不加#号),吸引眼球,控制在20字以内\\n- 正文用自然段落,中文流畅,结构清晰\\n- 适当补充背景知识让读者更好理解\\n- 去除原文中的来源链接和地址,不要出现链接\\n- 不要有任何解释或提示语,只输出文章内容\\n- 适合直接发布\\n\\n基于你提供的新闻链接及对应内容,完成一篇符合微信公众号发布标准的完整文章文案创作,具体要求如下:\\n1. 提炼1个吸睛、符合微信公众号传播逻辑的主标题,同时为正文所有核心段落提炼精准的段落小标题,所有段落正文围绕新闻核心信息展开创作,完整覆盖新闻的关键事实、核心亮点与延伸价值\\n2. 全程采用轻松活泼、愉快有趣的口语化文案语气,避免生硬的新闻播报感,加入符合年轻读者阅读习惯的网感表达,增强文案的可读性与传播性\\n3. 严格符合微信公众号常规文章的字数要求,总字数控制在1500-2500字区间,适配主流公众号读者的阅读时长,既不内容单薄也不因篇幅过长导致读者流失\\n4. 正文所有段落(包括主标题与引言段、各段落小标题与对应正文段之间)都单独占用一行,每两个段落之间保留一行空行隔开,排版逻辑清晰,符合公众号读者的竖屏阅读体验\\n5. 完成文案创作后,同步补充适配公众号的排版提示,包括重点内容的标注建议、合适的配图插入位置参考,确保文案可直接用于公众号的发布排版\\n6. 要文章大标题分明,段落小标题与上一个段落有两行的分隔行,段落要完整一段的完整起来,不要一小段一小段文字内容。\" }, { role: 'user', content: '标题:' + ($json.title || '') + '\\n链接:' + ($json.url || '') + '\\n评分:' + ($json.score || 8) + '/10\\n\\n原文内容:\\n' + ($json.content || '') } ], stream: false } }}",
        "options": {
          "timeout": 600000
        }
      },
      "id": "23809570-1c39-4214-b6fa-347b507d8c55",
      "name": "AI Agent1",
      "type": "n8n-nodes-base.httpRequest",
      "typeVersion": 4.2,
      "position": [
        1024,
        -336
      ],
      "credentials": {
        "openAiApi": {
          "id": "REPLACE_WITH_OPENAIAPI_CREDENTIAL_ID",
          "name": "请在 n8n 中重新选择对应凭证"
        }
      }
    },
    {
      "parameters": {
        "jsCode": "const generated = String($json.choices?.[0]?.message?.content || $json.output || '').trim();\nif (!generated) {\n  throw new Error('AI Agent1 returned an empty article');\n}\n\nconst source = $('Loop Over Items').item.json || {};\nconst firstLine = generated\n  .split('\\n')\n  .map((line) => line.trim())\n  .find(Boolean) || 'article';\nconst title = firstLine\n  .replace(/^#+\\s*/, '')\n  .replace(/\\*\\*/g, '')\n  .trim()\n  .slice(0, 64);\nconst sourceRunId = String(source.sourceRunId || '').trim();\nconst summaryDate = String(source.summaryDate || '').trim();\nconst normalizedTitle = title.toLowerCase().replace(/\\s+/g, ' ').slice(0, 140);\nconst articleKey = (sourceRunId + ':' + normalizedTitle).slice(0, 240);\n\nif (!sourceRunId || !articleKey) {\n  throw new Error('Missing Horizon source run ID for generated article');\n}\n\nreturn [{\n  json: {\n    article_key: articleKey,\n    source_run_id: sourceRunId,\n    summary_date: summaryDate,\n    title,\n    markdown: generated,\n    article_status: 'ready',\n    image_path: '',\n    image_status: 'pending',\n    wechat_status: 'pending',\n    wechat_media_id: '',\n    error: '',\n  },\n}];"
      },
      "id": "caf8f45d-b087-45ae-803f-3f0537bf6544",
      "name": "准备文章记录1",
      "type": "n8n-nodes-base.code",
      "typeVersion": 2,
      "position": [
        1280,
        -320
      ]
    },
    {
      "parameters": {
        "operation": "upsert",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "content_articles"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "article_key",
              "keyValue": "={{ $json.article_key }}"
            }
          ]
        },
        "columns": {
          "mappingMode": "defineBelow",
          "value": {
            "article_key": "={{ $json.article_key || '' }}",
            "source_run_id": "={{ $json.source_run_id || '' }}",
            "summary_date": "={{ $json.summary_date || '' }}",
            "title": "={{ $json.title || '' }}",
            "markdown": "={{ $json.markdown || '' }}",
            "article_status": "={{ $json.article_status || '' }}",
            "image_path": "={{ $json.image_path || '' }}",
            "image_status": "={{ $json.image_status || '' }}",
            "wechat_status": "={{ $json.wechat_status || '' }}",
            "wechat_media_id": "={{ $json.wechat_media_id || '' }}",
            "error": "={{ $json.error || '' }}"
          },
          "matchingColumns": [],
          "schema": [
            {
              "id": "article_key",
              "displayName": "article_key",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "source_run_id",
              "displayName": "source_run_id",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "summary_date",
              "displayName": "summary_date",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "title",
              "displayName": "title",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "markdown",
              "displayName": "markdown",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "article_status",
              "displayName": "article_status",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "image_path",
              "displayName": "image_path",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "image_status",
              "displayName": "image_status",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "wechat_status",
              "displayName": "wechat_status",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "wechat_media_id",
              "displayName": "wechat_media_id",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "error",
              "displayName": "error",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            }
          ],
          "attemptToConvertTypes": false,
          "convertFieldsToString": false
        },
        "options": {}
      },
      "id": "0c9b19a9-72af-4cb4-a0aa-c40c85829e5c",
      "name": "存储文章到 Data Table",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        1520,
        -320
      ]
    }
  ],
  "connections": {
    "Loop Over Items": {
      "main": [
        [],
        [
          {
            "node": "AI Agent1",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "Schedule Trigger1": {
      "main": [
        [
          {
            "node": "读取Horizon摘要1",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "读取Horizon摘要1": {
      "main": [
        [
          {
            "node": "解析Horizon1",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "解析Horizon1": {
      "main": [
        [
          {
            "node": "Loop Over Items",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "AI Agent1": {
      "main": [
        [
          {
            "node": "准备文章记录1",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "准备文章记录1": {
      "main": [
        [
          {
            "node": "存储文章到 Data Table",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "存储文章到 Data Table": {
      "main": [
        [
          {
            "node": "Loop Over Items",
            "type": "main",
            "index": 0
          }
        ]
      ]
    }
  },
  "settings": {
    "executionOrder": "v1",
    "binaryMode": "separate",
    "availableInMCP": true
  },
  "active": false,
  "pinData": {},
  "tags": []
}
工作流 3:生成文章封面(点击展开代码)
{
  "name": "生图",
  "nodes": [
    {
      "parameters": {},
      "id": "b30de4eb-140a-48f1-88e6-10515b2116d0",
      "name": "手动触发",
      "type": "n8n-nodes-base.manualTrigger",
      "typeVersion": 1,
      "position": [
        -144,
        -320
      ]
    },
    {
      "parameters": {
        "operation": "get",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "content_articles"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "article_status",
              "keyValue": "ready"
            },
            {
              "keyName": "image_status",
              "keyValue": "pending"
            }
          ]
        },
        "returnAll": true,
        "orderBy": true,
        "orderByDirection": "ASC"
      },
      "id": "19a5e131-b062-4cd4-86f2-4be7ff6975f3",
      "name": "读取文章",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        80,
        -320
      ]
    },
    {
      "parameters": {
        "jsCode": "return $input.all().map((item, index) => {\n  const row = item.json || {};\n  const title = String(row.title || '').trim();\n  const markdown = String(row.markdown || '');\n  const articleKey = String(row.article_key || '').trim();\n  if (!title || !articleKey) {\n    throw new Error('content_articles row is missing title or article_key');\n  }\n\n  const techTerms = markdown\n    .slice(0, 2500)\n    .match(/[A-Z][a-zA-Z]+(?:\\s+[A-Z][a-zA-Z]+)*/g) || [];\n  const keywords = [...new Set(\n    techTerms.map((term) => term.trim()).filter((term) => term.length > 2)\n  )].slice(0, 5);\n  const safeKey = articleKey\n    .replace(/[^a-zA-Z0-9\\u4e00-\\u9fff_-]+/g, '_')\n    .replace(/^_+|_+$/g, '')\n    .slice(0, 120) || ('article_' + (row.id || index));\n\n  return {\n    json: {\n      ...row,\n      imageFileName: safeKey + '.jpeg',\n      keywords: keywords.join(', '),\n    },\n    pairedItem: { item: index },\n  };\n});"
      },
      "id": "3ef0a405-5ff3-42f0-babd-d79e92accb41",
      "name": "提取标题",
      "type": "n8n-nodes-base.code",
      "typeVersion": 2,
      "position": [
        352,
        -320
      ]
    },
    {
      "parameters": {
        "operation": "write",
        "fileName": "=/home/node/.n8n-files/lmg/{{ $json.imageFileName }}",
        "options": {}
      },
      "id": "419e3f06-9a62-4199-807b-ece5ca9488df",
      "name": "保存图片",
      "type": "n8n-nodes-base.readWriteFile",
      "typeVersion": 1.1,
      "position": [
        1040,
        -320
      ]
    },
    {
      "parameters": {
        "rule": {
          "interval": [
            {
              "triggerAtHour": 9,
              "triggerAtMinute": 30
            }
          ]
        }
      },
      "type": "n8n-nodes-base.scheduleTrigger",
      "typeVersion": 1.3,
      "position": [
        -144,
        -144
      ],
      "id": "ab074fd9-d898-4928-a24f-bf9a75e02449",
      "name": "Schedule Trigger"
    },
    {
      "parameters": {
        "prompt": "=Please generate a high-quality pixel-style article cover image based on the title \"{{ $json.title }} \".\n\nThe image must accurately understand the theme, core event, involved brands, products, platforms, individuals, or technological scenarios expressed in the title, and extract a clear and eye-catching visual subject around the title. Do not simply create an abstract background; it must include main materials, event elements, and application scenarios directly related to the title.\n\nVisual Content Requirements:\n\n1. Automatically identify the brands, platforms, software, products, or services involved in the title and add the corresponding brand logo, application icon, device model, interface card, or iconic visual material. For example, if the title involves brands such as OpenAI, ChatGPT, Claude, Gemini, DeepSeek, WordPress, Shopify, Telegram, GitHub, n8n, Cloudflare, or Supabase, the corresponding and easily recognizable logo or icon should be presented.\n\n2. Design the visual storyline based on the event in the title. For example, product launches, system updates, platform partnerships, major breakthroughs, service launches, price adjustments, malfunctions, acquisitions, policy changes, or technological competition should be represented through elements such as human actions, product demonstrations, data panels, news cards, servers, chips, robots, code windows, arrows, warning symbols, and launch stages, rather than simply stacking logos.\n\n3. Choose a core element that best represents the title and place it in the center or at the visual focal point of the image. Other brand materials, icons, and event elements should be arranged in layers around the core. The core should stand out, and the background should be rich but not cluttered.\n\n4. The overall style should be a refined, high-pixel-density Pixel Art illustration style, combining the texture of classic video game covers with 16-bit and modern high-definition pixel art. Pixels should be clear, edges sharp, and details rich; avoid low-resolution, blurry, or rough mosaic effects.\n\n5. Use rich, bright, and highly saturated colors, prioritizing orange, red, yellow, gold, green, turquoise, off-white, and warm lighting. Blue and purple can be used sparingly in tech interfaces, shadows, or specific moods, but should not be the primary colors. Avoid large areas of blue-purple gradients, neon purple backgrounds, and common \"AI tech\" color schemes.\n\n6. Use warm and cool colors to create contrast, giving the image a vibrant, news-like feel and visual impact. You can add sunset orange light, gold particles, green data streams, red warning lights, and colored pixel lights, but avoid having all elements emit blue-purple neon light.\n\n7. The composition should be suitable for article covers and news header images, with clear layers, including the foreground subject, mid-ground event materials, and background environment. Backgrounds can be chosen based on the title, such as a tech office, press conference stage, data center, chip city, internet space, developer workbench, commercial district, or pixel world.\n\n8. Reserve a clear text area for the title. The title text should be eye-catching, easy to read, and maintain sufficient contrast with the background. The title content is:\n\n《{{ $json.title }}》\n\nThe text must be correct, without typos, garbled characters, repeated characters, or meaningless English. 9. Avoid generating unnecessary text beyond the designated title. Brand logos and icons should maintain correct basic outlines, color characteristics, and recognizability. Avoid arbitrary distortions, misspellings of brand names, or generating non-existent logos. When multiple brands appear simultaneously, their size and position should be determined according to their importance in the title, avoiding a large, uniform arrangement of all logos.\n\n10. The final image should possess the polish of a professional media cover, a tech news headline, or a commercial illustration. The information should be clear, narrative-driven, focused, and event-driven, rather than a simple logo collage or purely decorative background.\n\nKeywords: High-definition pixel art, modern pixel art, 16-bit game cover, rich detail, highly saturated colors, primary colors of orange, red, gold, and green, appropriate amounts of blue and purple, brand logo materials, application icons, event narrative, news cover, dynamic composition, strong visual center, clear text areas, professional commercial illustration.\n\n\nNegative requirements: Avoid large areas of purple and dark blue, avoid blue-purple gradient main backgrounds, avoid cheap AI neon style, avoid purely abstract technological backgrounds, avoid unclear subject matter, avoid simply stacking logos, avoid repetitive icons, avoid misspelling of brand names, avoid garbled text, avoid low-resolution pixel blocks, avoid blurriness, avoid excessive glow, avoid crowded images, avoid dark colors, avoid realistic photography style, and avoid 3D plastic texture.",
        "quality": "medium",
        "responseFormat": "url",
        "outputFormat": "jpeg",
        "timeoutSeconds": 120,
        "retryAttempts": 2,
        "retryWaitSeconds": 5
      },
      "type": "CUSTOM.imageRelay",
      "typeVersion": 1,
      "position": [
        784,
        -320
      ],
      "id": "da87c7f2-5786-4411-8279-7f061e157b02",
      "name": "生成封面图",
      "credentials": {
        "openAiApi": {
          "id": "REPLACE_WITH_OPENAIAPI_CREDENTIAL_ID",
          "name": "请在 n8n 中重新选择对应凭证"
        }
      }
    },
    {
      "parameters": {
        "options": {}
      },
      "type": "n8n-nodes-base.splitInBatches",
      "typeVersion": 3,
      "position": [
        560,
        -320
      ],
      "id": "313cf133-a0dd-4271-99e2-becebd12f37a",
      "name": "Loop Over Items"
    },
    {
      "parameters": {
        "operation": "update",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "content_articles"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "article_key",
              "keyValue": "={{ $json.article_key }}"
            }
          ]
        },
        "columns": {
          "mappingMode": "defineBelow",
          "value": {
            "image_path": "={{ $json.fileName }}",
            "image_status": "ready"
          },
          "matchingColumns": [],
          "schema": [
            {
              "id": "image_path",
              "displayName": "image_path",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "image_status",
              "displayName": "image_status",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            },
            {
              "id": "error",
              "displayName": "error",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "canBeUsedToMatch": true
            }
          ],
          "attemptToConvertTypes": false,
          "convertFieldsToString": false
        },
        "options": {}
      },
      "id": "b95ff808-72c3-4e41-9dc7-37ccd48a8b25",
      "name": "更新图片状态",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        1280,
        -320
      ]
    }
  ],
  "connections": {
    "手动触发": {
      "main": [
        [
          {
            "node": "读取文章",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "读取文章": {
      "main": [
        [
          {
            "node": "提取标题",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "提取标题": {
      "main": [
        [
          {
            "node": "Loop Over Items",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "保存图片": {
      "main": [
        [
          {
            "node": "更新图片状态",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "Schedule Trigger": {
      "main": [
        [
          {
            "node": "读取文章",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "生成封面图": {
      "main": [
        [
          {
            "node": "保存图片",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "Loop Over Items": {
      "main": [
        [],
        [
          {
            "node": "生成封面图",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "更新图片状态": {
      "main": [
        [
          {
            "node": "Loop Over Items",
            "type": "main",
            "index": 0
          }
        ]
      ]
    }
  },
  "settings": {
    "executionOrder": "v1",
    "binaryMode": "separate",
    "availableInMCP": true
  },
  "active": false,
  "pinData": {},
  "tags": []
}
工作流 4:排版并推送微信公众号草稿(点击展开代码)
{
"name": "推送微信草稿",
"nodes": [
{
"parameters": {},
"id": "fe66e5cc-84ae-4258-8fe4-67bfd49a76d8",
"name": "手动触发",
"type": "n8n-nodes-base.manualTrigger",
"typeVersion": 1,
"position": [
2176,
-224
]
},
{
"parameters": {
"operation": "get",
"dataTableId": {
"__rl": true,
"value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
"mode": "list",
"cachedResultName": "content_articles"
},
"matchType": "allConditions",
"filters": {
"conditions": [
{
"keyName": "article_status",
"keyValue": "ready"
},
{
"keyName": "image_status",
"keyValue": "ready"
}
]
},
"limit": 8,
"orderBy": true,
"orderByDirection": "ASC"
},
"id": "03af783b-dc32-452f-bb85-cb4340bb7d19",
"name": "读取文章",
"type": "n8n-nodes-base.dataTable",
"typeVersion": 1.1,
"position": [
1936,
32
]
},
{
"parameters": {},
"id": "4d80edfd-35c6-48a0-9d7a-54802d95329d",
"name": "合并数据",
"type": "n8n-nodes-base.merge",
"typeVersion": 3.2,
"position": [
2640,
160
]
},
{
"parameters": {
"fileSelector": "={{ $json.image_path }}",
"options": {}
},
"id": "66be3f95-95b2-41c7-83b7-083d688ac4ae",
"name": "读取封面图",
"type": "n8n-nodes-base.readWriteFile",
"typeVersion": 1.1,
"position": [
1936,
288
]
},
{
"parameters": {
"jsCode": "const articles = $('尾图').all()\n .filter((item) => item.json.itemType === 'article');\nconst covers = $('提取封面ID').all()\n .filter((item) => item.json.itemType === 'cover');\n\nif (articles.length === 0) {\n throw new Error('没有找到待推送文章,请检查 content_articles。');\n}\nif (covers.length === 0) {\n throw new Error('没有找到微信封面 media_id,请检查封面上传。');\n}\nif (articles.length > 8) {\n throw new Error('微信公众号单个草稿最多包含 8 篇文章,当前为 ' + articles.length + ' 篇。');\n}\n\nconst coverMap = Object.fromEntries(\n covers.map((cover) => [\n String(cover.json.article_key || ''),\n String(cover.json.thumb_media_id || ''),\n ])\n);\nconst failures = [];\nconst draftArticles = [];\nconst articleMeta = [];\n\nfor (const article of articles) {\n const articleKey = String(article.json.article_key || '').trim();\n const content = String(article.json.content || '');\n const title = String(article.json.title || '').trim();\n const thumbMediaId = coverMap[articleKey];\n\n if (!articleKey || !thumbMediaId) {\n failures.push({ article_key: articleKey, title, error: '找不到对应封面 media_id' });\n continue;\n }\n if (!content) {\n failures.push({ article_key: articleKey, title, error: '文章内容为空' });\n continue;\n }\n\n const digest = content\n .replace(/<[^>]+>/g, '')\n .replace(/\\s+/g, ' ')\n .slice(0, 120)\n .trim();\n draftArticles.push({\n title,\n author: 'HF Daily',\n digest,\n show_cover_pic: 1,\n content,\n content_source_url: 'https://macosabc.com/token',\n thumb_media_id: thumbMediaId,\n });\n articleMeta.push({\n article_key: articleKey,\n title,\n thumb_media_id: thumbMediaId,\n });\n}\n\nif (failures.length > 0) {\n throw new Error('准备微信草稿失败:' + JSON.stringify(failures));\n}\nif (draftArticles.length === 0) {\n throw new Error('没有可推送的草稿文章。');\n}\n\nreturn [{\n json: {\n articles_json: JSON.stringify(draftArticles),\n article_count: draftArticles.length,\n cover_count: covers.length,\n article_keys: articleMeta.map((item) => item.article_key),\n titles: articleMeta.map((item) => item.title),\n thumb_media_ids: articleMeta.map((item) => item.thumb_media_id),\n },\n}];"
},
"id": "3baed53b-afe4-40b0-8e7e-93099474b8c2",
"name": "准备微信草稿数据",
"type": "n8n-nodes-base.code",
"typeVersion": 2,
"position": [
2896,
160
]
},
{
"parameters": {
"resource": "media",
"operation": "media:uploadOther"
},
"id": "2ea8b59c-87e4-4d1c-a2be-1aec40ae20c7",
"name": "上传封面到微信",
"type": "n8n-nodes-wechat-offiaccount.wechatOfficialAccountNode",
"typeVersion": 1,
"position": [
2160,
288
],
"credentials": {
"wechatOfficialAccountCredentialsApi": {
"id": "REPLACE_WITH_WECHATOFFICIALACCOUNTCREDENTIALSAPI_CREDENTIAL_ID",
"name": "请在 n8n 中重新选择对应凭证"
}
}
},
{
"parameters": {
"jsCode": "const articles = $('读取文章').all();\nconst uploads = $input.all();\n\nreturn uploads.map((upload, index) => {\n const article = articles[index]?.json || {};\n const mediaId = String(upload.json.media_id || '').trim();\n const articleKey = String(article.article_key || '').trim();\n if (!mediaId || !articleKey) {\n throw new Error('Cover upload is missing media_id or article_key at index ' + index);\n }\n return {\n json: {\n itemType: 'cover',\n article_key: articleKey,\n title: article.title || '',\n thumb_media_id: mediaId,\n },\n };\n});"
},
"id": "a295dfc4-2ec6-4c3d-baca-873eb74e17d6",
"name": "提取封面ID",
"type": "n8n-nodes-base.code",
"typeVersion": 2,
"position": [
2384,
288
]
},
{
"parameters": {
"jsCode": "\nconst allItems = $input.all();\nconst results = [];\nconst failed = [];\n\nfor (let i = 0; i < allItems.length; i++) {\n try {\n let content = String(allItems[i].json.markdown || '').trim();\n const articleKey = String(allItems[i].json.article_key || '').trim();\n const imagePath = String(allItems[i].json.image_path || '').trim();\n const fileName = articleKey ? articleKey + '.md' : 'article.md';\n let title = String(allItems[i].json.title || '').trim().slice(0, 64);\n\n if (!content || !articleKey || !title || !imagePath) {\n throw new Error('Data Table article is missing markdown, article_key, title, or image_path');\n }\n\n const isLayoutTipHeading = (line) => {\n const normalized = line\n .trim()\n .replace(/^[-*#>\\s]+/, '')\n .replace(/^\\d+[.)、]\\s*/, '')\n .replace(/\\*\\*/g, '')\n .replace(/[<《【\\[]/g, '')\n .replace(/[>》】\\]]/g, '');\n return /^(公众号)?(排版提示建议|排版提示|排版建议|排版贴士)([::].*)?$/.test(normalized);\n };\n\n const rawLines = content.split('\\n');\n const tipLineIdx = rawLines.findIndex(isLayoutTipHeading);\n const layoutTipMarker = /(排版提示|排版建议|排版贴士|配图位置建议|配图插入位置参考|重点内容标注建议|文末引导语|图片来源建议)/;\n const markerLineIdx = rawLines.findIndex((line) => layoutTipMarker.test(line));\n const cutLineIdx = [tipLineIdx, markerLineIdx].filter((idx) => idx > -1).sort((a, b) => a - b)[0] ?? -1;\n if (cutLineIdx > -1) {\n let beforeLines = rawLines.slice(0, cutLineIdx);\n while (beforeLines.length > 0) {\n const last = beforeLines[beforeLines.length - 1].trim();\n if (last === '---' || last === '') beforeLines.pop();\n else break;\n }\n content = beforeLines.join('\\n').trimEnd();\n }\n\n const codeBlocks = [];\n content = content.replace(/```[\\s\\S]*?```/g, (match) => {\n codeBlocks.push(match);\n return `__CODE_BLOCK_${codeBlocks.length - 1}__`;\n });\n\n let lines = content.split('\\n');\n let blocks = [];\n let currentParagraph = [];\n let firstNonEmpty = true;\n\n const flushParagraph = () => {\n if (currentParagraph.length > 0) {\n blocks.push({ type: 'paragraph', text: currentParagraph.join(' ').replace(/\\s+/g, ' ').trim() });\n currentParagraph = [];\n }\n };\n\n for (let idx = 0; idx < lines.length; idx++) {\n const trimmed = lines[idx].trim();\n\n if (/^---+\\s*$/.test(trimmed)) {\n flushParagraph();\n continue;\n }\n\n if (firstNonEmpty && trimmed.length > 0) {\n firstNonEmpty = false;\n continue;\n }\n\n if (/^#{1,6}\\s+/.test(trimmed)) {\n flushParagraph();\n blocks.push({\n type: 'subtitle',\n text: trimmed.replace(/^#{1,6}\\s+/, '').replace(/\\*\\*/g, '').trim()\n });\n continue;\n }\n\n if (/^[-*]\\s+/.test(trimmed)) {\n flushParagraph();\n blocks.push({ type: 'list', text: trimmed.replace(/^[-*]\\s+/, '') });\n continue;\n }\n\n if (trimmed === '') {\n flushParagraph();\n continue;\n }\n\n if (/^__CODE_BLOCK_\\d+__$/.test(trimmed)) {\n flushParagraph();\n const idxNum = parseInt(trimmed.match(/\\d+/)[0]);\n blocks.push({ type: 'code', text: codeBlocks[idxNum] });\n continue;\n }\n\n currentParagraph.push(trimmed);\n }\n flushParagraph();\n\n blocks = blocks.map((block) => {\n if (block.type !== 'paragraph') return block;\n\n const text = block.text;\n\n if (/^第[一二三四五六七八九十0-9]+[个类章节部分]/.test(text.trim())) {\n return block;\n }\n\n const match = text.match(/^([^\\s。!?!?]{2,25}?[::??])\\s*(.*)$/s);\n if (match && match[1].length <= 25 && match[1].length >= 4) {\n if (/^[一二三四五六七八九十0-9]+类[::]$/.test(match[1])) {\n return block;\n }\n const subtitleText = match[1].trim();\n const rest = match[2].trim();\n if (rest.length > 0) {\n return [\n { type: 'subtitle', text: subtitleText },\n { type: 'paragraph', text: rest }\n ];\n } else {\n return [{ type: 'subtitle', text: subtitleText }];\n }\n }\n return block;\n }).flat();\n\n blocks = (() => {\n const result = [];\n for (let j = 0; j < blocks.length; j++) {\n const cur = blocks[j];\n const next = blocks[j + 1];\n if (\n cur.type === 'subtitle' &&\n next && next.type === 'paragraph' &&\n next.text.length <= 12 &&\n !/[。!!.,,]/.test(next.text)\n ) {\n result.push({ type: 'subtitle', text: cur.text + next.text });\n j++;\n } else {\n result.push(cur);\n }\n }\n return result;\n })();\n\n let finalBlocks = [];\n for (let j = 0; j < blocks.length; j++) {\n const cur = blocks[j];\n const prev = finalBlocks[finalBlocks.length - 1];\n\n if (cur.type !== 'paragraph') {\n finalBlocks.push(cur);\n continue;\n }\n\n const isVeryShort = cur.text.length < 15;\n if (prev && prev.type === 'paragraph' && cur.text.length < 80 && !cur.text.endsWith(':') && !cur.text.endsWith(':') && !cur.text.endsWith('?') && !cur.text.endsWith('?')) {\n prev.text = prev.text + ' ' + cur.text;\n continue;\n }\n if (prev && prev.type === 'paragraph' && isVeryShort) {\n prev.text = prev.text + cur.text;\n continue;\n }\n\n finalBlocks.push(cur);\n }\n\n const renderParagraph = (text) => {\n text = text.replace(/__CODE_BLOCK_(\\d+)__/g, (m, idx) => codeBlocks[parseInt(idx)] || '');\n return text.replace(/\\*\\*([^*]+)\\*\\*/g, '<strong>$1</strong>');\n };\n\n let html = '';\n for (const block of finalBlocks) {\n if (block.type === 'subtitle') {\n html += '<p style=\"font-weight:bold;font-size:16px;margin:30px 0 10px 0;line-height:1.6;color:#333;\">' + escapeHtml(block.text.replace(/\\*\\*/g, '').trim()) + '</p>\\n';\n } else if (block.type === 'list') {\n const itemText = renderParagraph(block.text);\n html += '<p style=\"text-indent:0;margin:5px 0 5px 18px;line-height:1.8;font-size:16px;color:#333;\">\\u00b7 ' + itemText + '</p>\\n';\n } else if (block.type === 'code') {\n html += '<pre style=\"background:#f5f5f5;padding:12px;border-radius:4px;overflow-x:auto;font-size:14px;line-height:1.5;margin:15px 0;\">' + escapeHtml(block.text) + '</pre>\\n';\n } else if (block.type === 'paragraph') {\n const paraText = renderParagraph(block.text);\n html += '<p style=\"text-indent:0;margin:15px 0;line-height:1.8;font-size:16px;color:#333;\">' + paraText + '</p>\\n';\n }\n }\n\n if (!html.trim()) {\n failed.push({ fileName, error: 'Empty content after formatting' });\n continue;\n }\n\n const assertions = {\n hasFontSize16: /font-size:16px/.test(html),\n hasMargin30: /margin:30px 0 10px 0/.test(html),\n hasBoldWeight: /font-weight:bold/.test(html),\n hasColor333: /color:#333/.test(html),\n hasSubtitles: (html.match(/font-weight:bold[^\"]*\">[^<]+/g) || []).length >= 1,\n noLayoutTipResidue: !/(排版提示|排版建议|排版贴士|配图插入位置参考|重点内容标注建议)/.test(html)\n };\n const failed_asserts = Object.entries(assertions).filter(([k, v]) => !v).map(([k]) => k);\n if (failed_asserts.length > 0) {\n failed.push({ fileName, error: 'Assertion failed: ' + failed_asserts.join(', ') });\n continue;\n }\n\n const htmlContent = '<div style=\"font-size:16px;color:#333;\">\\n' + html + '</div>';\n results.push({\n json: {\n content: htmlContent,\n title,\n fileName,\n itemType: 'article',\n formatted: true,\n article_key: articleKey,\n image_path: imagePath\n },\n pairedItem: { item: i }\n });\n } catch (err) {\n failed.push({ fileName: allItems[i].json.fileName || `item_${i}`, error: err.message, stack: err.stack });\n }\n}\n\nfunction escapeHtml(text) {\n return String(text)\n .replace(/&/g, '&')\n .replace(/</g, '<')\n .replace(/>/g, '>')\n .replace(/\"/g, '"');\n}\n\nif (failed.length > 0) {\n console.log('[format-v3.1] Failed items:', JSON.stringify(failed));\n throw new Error('Some articles failed to format: ' + JSON.stringify(failed));\n}\n\nif (results.length === 0) {\n throw new Error('All articles failed to format: ' + JSON.stringify(failed));\n}\n\nreturn results;\n"
},
"id": "361c7392-11d6-4d24-a40c-84b42b495a0c",
"name": "文章格式处理",
"type": "n8n-nodes-base.code",
"typeVersion": 1,
"position": [
2144,
32
]
},
{
"parameters": {
"rule": {
"interval": [
{
"triggerAtHour": 10,
"triggerAtMinute": 20
}
]
}
},
"type": "n8n-nodes-base.scheduleTrigger",
"typeVersion": 1.3,
"position": [
2144,
480
],
"id": "241414c8-684e-4fca-853d-7de8223a081a",
"name": "Schedule Trigger"
},
{
"parameters": {
"resource": "draft",
"operation": "draft:add",
"articles": "={{ $json.articles_json }}"
},
"type": "n8n-nodes-wechat-offiaccount.wechatOfficialAccountNode",
"typeVersion": 1,
"position": [
3184,
160
],
"id": "aa7b3cb2-493b-4fb3-b9e8-89766f3bfde5",
"name": "推送微信公众号草稿",
"credentials": {
"wechatOfficialAccountCredentialsApi": {
"id": "REPLACE_WITH_WECHATOFFICIALACCOUNTCREDENTIALSAPI_CREDENTIAL_ID",
"name": "请在 n8n 中重新选择对应凭证"
}
}
},
{
"parameters": {
"jsCode": "const response = $input.first().json || {};\nconst prepared = $('准备微信草稿数据').first().json || {};\nconst mediaId = String(response.media_id || response.mediaId || '').trim();\nconst articleKeys = Array.isArray(prepared.article_keys)\n ? prepared.article_keys\n : [];\n\nif (!mediaId || articleKeys.length === 0) {\n throw new Error('WeChat draft response is missing media_id or article_keys');\n}\n\nreturn articleKeys.map((articleKey) => ({\n json: {\n article_key: articleKey,\n wechat_status: 'drafted',\n wechat_media_id: mediaId,\n error: '',\n },\n}));"
},
"id": "282ac107-8e3b-48e8-822e-8a5340c5ae78",
"name": "准备草稿回写",
"type": "n8n-nodes-base.code",
"typeVersion": 2,
"position": [
3424,
160
]
},
{
"parameters": {
"operation": "update",
"dataTableId": {
"__rl": true,
"value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
"mode": "list",
"cachedResultName": "content_articles"
},
"matchType": "allConditions",
"filters": {
"conditions": [
{
"keyName": "article_key",
"keyValue": "={{ $json.article_key }}"
}
]
},
"columns": {
"mappingMode": "defineBelow",
"value": {
"wechat_status": "drafted",
"wechat_media_id": "={{ $json.wechat_media_id }}"
},
"matchingColumns": [],
"schema": [
{
"id": "wechat_status",
"displayName": "wechat_status",
"required": false,
"defaultMatch": false,
"display": true,
"type": "string",
"canBeUsedToMatch": true
},
{
"id": "wechat_media_id",
"displayName": "wechat_media_id",
"required": false,
"defaultMatch": false,
"display": true,
"type": "string",
"canBeUsedToMatch": true
},
{
"id": "error",
"displayName": "error",
"required": false,
"defaultMatch": false,
"display": true,
"type": "string",
"canBeUsedToMatch": true
}
],
"attemptToConvertTypes": false,
"convertFieldsToString": false
},
"options": {}
},
"id": "99b1b2ad-a1c5-46e5-9f01-9e4bd3f02562",
"name": "更新微信草稿状态",
"type": "n8n-nodes-base.dataTable",
"typeVersion": 1.1,
"position": [
3664,
160
]
},
{
"parameters": {
"jsCode": "const allItems = $input.all();\nconst results = [];\n\nconst tailImageUrl = 'https://mmecoa.qpic.cn/mmecoa_png/s0D2micbQKRM0dt70EZP2H0S5dIOrEQvuarNziakPpmiab3eVBarCH5GLAlBgC2MFCez3sM3MxN1pYj7BEtUd9obF3mVDvmTbfibUAS02L3c71I/640?wx_fmt=png&from=appmsg';\nconst tailLinkUrl = 'https://macosabc.com/token';\n\nconst escapedImageUrl = tailImageUrl.replace(/&/g, '&');\n\nconst tailHtml = `<section style=\"margin:0;padding:0;line-height:0;font-size:0;\">\n <a\n href=\"${tailLinkUrl}\"\n target=\"_blank\"\n linktype=\"image\"\n style=\"display:block;margin:0;padding:0;line-height:0;text-decoration:none;-webkit-tap-highlight-color:rgba(0,0,0,0);\">\n <img\n src=\"${escapedImageUrl}\"\n data-src=\"${escapedImageUrl}\"\n data-type=\"png\"\n data-w=\"640\"\n style=\"display:block;width:100%;height:auto;margin:0;padding:0;border:0;vertical-align:top;\"\n alt=\"插图\" />\n </a>\n</section>`;\n\nfor (let i = 0; i < allItems.length; i++) {\n let content = allItems[i].json.content || '';\n const lastCloseDiv = content.lastIndexOf('</div>');\n\n if (lastCloseDiv !== -1) {\n content = content.slice(0, lastCloseDiv) + '\\n' + tailHtml + '\\n' + content.slice(lastCloseDiv);\n } else {\n content += '\\n' + tailHtml;\n }\n\n results.push({\n json: {\n ...allItems[i].json,\n content,\n },\n binary: allItems[i].binary,\n pairedItem: {\n item: i,\n },\n });\n}\n\nreturn results;"
},
"id": "e67f1411-a2d9-4653-b77b-5d29cdcc1b8e",
"name": "尾图2333",
"type": "n8n-nodes-base.code",
"typeVersion": 2,
"position": [
2384,
-96
]
},
{
"parameters": {
"jsCode": "const allItems = $input.all();\nconst results = [];\n\nconst tailHtml = `<section style=\"margin-top:30px;text-align:center;\">\n <svg\n width=\"100%\"\n style=\"display:block;background-image:url("https://mmbiz.qpic.cn/mmbiz_png/h7iaUtRYxuJEd9mmcbk8vTBjbK9UFhqic65AztWNJsv7PMUsbdY4LuBcSvTI6uk3lTQATNJP1RM30jObFevbfjdH7rlLMP1ExyzNibiaVgjNMoo/640?wx_fmt=png&from=appmsg");background-size:cover;pointer-events:initial;\"\n viewBox=\"0 0 1080 2844\"\n data-lazy-bgimg=\"https://mmbiz.qpic.cn/mmbiz_png/h7iaUtRYxuJEd9mmcbk8vTBjbK9UFhqic65AztWNJsv7PMUsbdY4LuBcSvTI6uk3lTQATNJP1RM30jObFevbfjdH7rlLMP1ExyzNibiaVgjNMoo/640?wx_fmt=png&from=appmsg\"\n role=\"img\"\n aria-label=\"插图\"\n data-fail=\"0\">\n <a\n data-miniprogram-appid=\"wx531d2c5a332558d6\"\n data-miniprogram-path=\"pages/index/index\"\n style=\"color:rgb(0,112,201);pointer-events:initial;\"\n class=\"weapp_text_link wx_tap_link js_wx_tap_highlight\"\n href=\"\"\n link-id=\"711c\">\n <rect x=\"300\" y=\"737\" width=\"480\" height=\"160\" fill=\"transparent\" style=\"pointer-events:initial;\"></rect>\n </a>\n </svg>\n</section>`;\n\nfor (let i = 0; i < allItems.length; i++) {\n let content = allItems[i].json.content || '';\n const lastCloseDiv = content.lastIndexOf('</div>');\n\n if (lastCloseDiv !== -1) {\n content = content.slice(0, lastCloseDiv) + '\\n' + tailHtml + '\\n' + content.slice(lastCloseDiv);\n } else {\n content += '\\n' + tailHtml;\n }\n\n results.push({\n json: {\n ...allItems[i].json,\n content,\n },\n binary: allItems[i].binary,\n pairedItem: {\n item: i,\n },\n });\n}\n\nreturn results;"
},
"id": "56050d85-5af0-458d-86ee-49ddb46f093c",
"name": "尾图",
"type": "n8n-nodes-base.code",
"typeVersion": 2,
"position": [
2384,
48
]
}
],
"connections": {
"手动触发": {
"main": [
[
{
"node": "读取文章",
"type": "main",
"index": 0
}
]
]
},
"读取文章": {
"main": [
[
{
"node": "文章格式处理",
"type": "main",
"index": 0
},
{
"node": "读取封面图",
"type": "main",
"index": 0
}
]
]
},
"合并数据": {
"main": [
[
{
"node": "准备微信草稿数据",
"type": "main",
"index": 0
}
]
]
},
"读取封面图": {
"main": [
[
{
"node": "上传封面到微信",
"type": "main",
"index": 0
}
]
]
},
"准备微信草稿数据": {
"main": [
[
{
"node": "推送微信公众号草稿",
"type": "main",
"index": 0
}
]
]
},
"上传封面到微信": {
"main": [
[
{
"node": "提取封面ID",
"type": "main",
"index": 0
}
]
]
},
"提取封面ID": {
"main": [
[
{
"node": "合并数据",
"type": "main",
"index": 1
}
]
]
},
"文章格式处理": {
"main": [
[
{
"node": "尾图",
"type": "main",
"index": 0
}
]
]
},
"Schedule Trigger": {
"main": [
[
{
"node": "读取文章",
"type": "main",
"index": 0
}
]
]
},
"推送微信公众号草稿": {
"main": [
[
{
"node": "准备草稿回写",
"type": "main",
"index": 0
}
]
]
},
"准备草稿回写": {
"main": [
[
{
"node": "更新微信草稿状态",
"type": "main",
"index": 0
}
]
]
},
"尾图": {
"main": [
[
{
"node": "合并数据",
"type": "main",
"index": 0
}
]
]
}
},
"settings": {
"executionOrder": "v1",
"availableInMCP": true,
"binaryMode": "separate",
"timeSavedMode": "fixed",
"callerPolicy": "workflowsFromSameOwner"
},
"active": false,
"pinData": {},
"tags": []
}工作流 5:当天数据与图片清理(点击展开代码)
{
  "name": "格式化",
  "nodes": [
    {
      "parameters": {},
      "id": "a9e0e97c-9a33-4151-920a-ec35f1ae1505",
      "name": "手动触发",
      "type": "n8n-nodes-base.manualTrigger",
      "typeVersion": 1,
      "position": [
        -736,
        80
      ]
    },
    {
      "parameters": {
        "rule": {
          "interval": [
            {
              "triggerAtHour": 23,
              "triggerAtMinute": 20
            }
          ]
        }
      },
      "id": "1f78c0d7-e063-43cb-95c9-6502a222dcd8",
      "name": "每日 23:20",
      "type": "n8n-nodes-base.scheduleTrigger",
      "typeVersion": 1.3,
      "position": [
        -736,
        -160
      ]
    },
    {
      "parameters": {
        "operation": "get",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "content_articles"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "summary_date",
              "keyValue": "={{ $now.format('yyyy-MM-dd') }}"
            }
          ]
        },
        "returnAll": true
      },
      "id": "aec55e3b-0921-4ae5-b0bb-cb49dc90cc19",
      "name": "读取当天文章与图片路径",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "alwaysOutputData": true,
      "position": [
        -416,
        -32
      ]
    },
    {
      "parameters": {
        "jsCode": "const rows = $input.all().map((item) => item.json || {}).filter((row) => Object.keys(row).length > 0);\nconst parts = new Intl.DateTimeFormat('en-US', {\n  timeZone: 'Asia/Shanghai',\n  year: 'numeric',\n  month: '2-digit',\n  day: '2-digit',\n}).formatToParts(new Date());\nconst part = Object.fromEntries(parts.map(({ type, value }) => [type, value]));\nconst cleanupDate = `${part.year}-${part.month}-${part.day}`;\nconst accepted = [];\nconst ignored = [];\nfor (const row of rows) {\n  const rawPath = String(row.image_path || '').trim().replace(/\\\\/g, '/');\n  if (!rawPath) continue;\n  const isAllowed = rawPath.startsWith('/home/node/.n8n-files/lmg/') || rawPath.startsWith('lmg/');\n  const isTraversal = rawPath.includes('/../') || rawPath.endsWith('/..');\n  if (!isAllowed || isTraversal) {\n    ignored.push(rawPath);\n    continue;\n  }\n  accepted.push(rawPath);\n}\nconst imagePaths = [...new Set(accepted)];\nconst encodedPaths = imagePaths\n  .map((filePath) => Buffer.from(filePath, 'utf8').toString('base64'))\n  .join(' ');\nreturn [{\n  json: {\n    cleanup_date: cleanupDate,\n    article_rows: rows.length,\n    image_paths: imagePaths,\n    encoded_paths: encodedPaths,\n    ignored_paths: ignored,\n  },\n}];"
      },
      "id": "ac81ad90-c97c-4e16-94fd-b61799ae4a9d",
      "name": "收集并校验当天图片路径",
      "type": "n8n-nodes-base.code",
      "typeVersion": 2,
      "position": [
        -128,
        -32
      ]
    },
    {
      "parameters": {
        "operation": "deleteRows",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_HORIZON_SUMMARIES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "horizon_summaries"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "condition": "gt",
              "keyValue": "0"
            }
          ]
        },
        "options": {}
      },
      "id": "5c7a9722-4e47-4e18-9b9b-4ccfb27cd891",
      "name": "删除当天 Horizon 摘要",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        208,
        -416
      ]
    },
    {
      "parameters": {
        "operation": "deleteRows",
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
          "mode": "list",
          "cachedResultName": "content_articles"
        },
        "matchType": "allConditions",
        "filters": {
          "conditions": [
            {
              "keyName": "summary_date",
              "keyValue": "={{ $json.cleanup_date }}"
            }
          ]
        },
        "options": {}
      },
      "id": "9e3589ca-ff2c-4c00-a5c7-7b2dd78c7df7",
      "name": "删除当天文章",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        208,
        -176
      ]
    },
    {
      "parameters": {
        "command": "=set -eu; dir='lmg'; day='{{ $json.cleanup_date }}'; compact=$(printf '%s' \"$day\" | tr -d '-'); [ -d \"$dir\" ] || { echo \"目录不存在: $dir\" >&2; exit 1; }; deleted=0; encoded_paths='{{ $json.encoded_paths }}'; for encoded in $encoded_paths; do file=$(printf '%s' \"$encoded\" | base64 -d); case \"$file\" in /home/node/.n8n-files/lmg/*|lmg/*) if [ -f \"$file\" ]; then rm -f -- \"$file\"; deleted=$((deleted + 1)); fi ;; *) echo \"拒绝删除非 lmg 路径: $file\" >&2; exit 1 ;; esac; done; for pattern in \"${day}*\" \"${compact}*\"; do for file in \"$dir\"/$pattern; do [ -f \"$file\" ] || continue; case \"$(basename \"$file\")\" in .DS_Store|.gitkeep) continue ;; esac; rm -f -- \"$file\"; deleted=$((deleted + 1)); done; done; printf '{\"date\":\"%s\",\"deleted_images\":%s,\"article_rows\":%s}\\n' \"$day\" \"$deleted\" '{{ $json.article_rows }}'"
      },
      "id": "c8fce0eb-72f2-4005-9b65-6fe6d5e75668",
      "name": "删除当天实际图片",
      "type": "n8n-nodes-base.executeCommand",
      "typeVersion": 1,
      "position": [
        208,
        64
      ]
    },
    {
      "parameters": {
        "command": "=set -eu; dir='horizon/data/summaries/archive'; day='{{ $json.cleanup_date }}'; if [ ! -d \"$dir\" ]; then printf '{\"date\":\"%s\",\"deleted_summaries\":0,\"remaining\":0,\"directory_missing\":true}\\n' \"$day\"; exit 0; fi; before=$(find \"$dir\" -maxdepth 1 -type f -name \"horizon-${day}-*.md\" | wc -l | tr -d ' '); find \"$dir\" -maxdepth 1 -type f -name \"horizon-${day}-*.md\" -delete; after=$(find \"$dir\" -maxdepth 1 -type f -name \"horizon-${day}-*.md\" | wc -l | tr -d ' '); printf '{\"date\":\"%s\",\"deleted_summaries\":%s,\"remaining\":%s,\"directory_missing\":false}\\n' \"$day\" \"$before\" \"$after\""
      },
      "id": "c3e7533c-bace-4b20-a0b1-28b6ed3b409e",
      "name": "删除当天摘要文件",
      "type": "n8n-nodes-base.executeCommand",
      "typeVersion": 1,
      "position": [
        208,
        304
      ]
    },
    {
      "parameters": {
        "content": "## 只清理当天数据\n按 **Asia/Shanghai** 当天日期执行:\n\n1. 读取 `content_articles` 当天记录并校验图片路径\n2. 删除 `horizon_summaries` 当天记录\n3. 删除 `content_articles` 当天记录\n4. 删除记录指向的 `lmg` 实际图片,并补删当天日期前缀的孤儿图片\n5. 删除当天 `horizon-YYYY-MM-DD-*.md` 摘要归档\n\n不会清理历史日期,也不再清理旧 `articles/` 目录。路径异常会直接失败。",
        "height": 464,
        "width": 432,
        "color": 5
      },
      "id": "e54493ea-7058-4dd4-83e8-ae6f31e7ea70",
      "name": "清理说明",
      "type": "n8n-nodes-base.stickyNote",
      "typeVersion": 1,
      "position": [
        464,
        -256
      ]
    }
  ],
  "connections": {
    "手动触发": {
      "main": [
        [
          {
            "node": "读取当天文章与图片路径",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "每日 23:20": {
      "main": [
        [
          {
            "node": "读取当天文章与图片路径",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "读取当天文章与图片路径": {
      "main": [
        [
          {
            "node": "收集并校验当天图片路径",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "收集并校验当天图片路径": {
      "main": [
        [
          {
            "node": "删除当天 Horizon 摘要",
            "type": "main",
            "index": 0
          },
          {
            "node": "删除当天文章",
            "type": "main",
            "index": 0
          },
          {
            "node": "删除当天实际图片",
            "type": "main",
            "index": 0
          },
          {
            "node": "删除当天摘要文件",
            "type": "main",
            "index": 0
          }
        ]
      ]
    }
  },
  "settings": {
    "executionOrder": "v1",
    "availableInMCP": true,
    "binaryMode": "separate",
    "timezone": "Asia/Shanghai"
  },
  "active": false,
  "pinData": {},
  "tags": []
}
工作流 6:WordPress 最新文章摘要(点击展开代码)
{
  "name": "wordpress",
  "nodes": [
    {
      "parameters": {},
      "id": "manual-trigger-wordpress",
      "name": "手动触发",
      "type": "n8n-nodes-base.manualTrigger",
      "typeVersion": 1,
      "position": [
        160,
        240
      ]
    },
    {
      "parameters": {
        "rule": {
          "interval": [
            {
              "triggerAtHour": 7,
              "triggerAtMinute": 30
            }
          ]
        }
      },
      "id": "schedule-trigger-wordpress",
      "name": "每日 07:30",
      "type": "n8n-nodes-base.scheduleTrigger",
      "typeVersion": 1.3,
      "position": [
        160,
        400
      ]
    },
    {
      "parameters": {
        "url": "https://hfz.pw/wp-json/wp/v2/posts?per_page=1&orderby=date&order=desc&_embed=1",
        "authentication": "predefinedCredentialType",
        "nodeCredentialType": "wordpressApi",
        "options": {}
      },
      "id": "fetch-latest-wordpress-post",
      "name": "博客网址与应用密钥",
      "type": "n8n-nodes-base.httpRequest",
      "typeVersion": 4.2,
      "position": [
        400,
        320
      ],
      "credentials": {
        "wordpressApi": {
          "id": "REPLACE_WITH_WORDPRESSAPI_CREDENTIAL_ID",
          "name": "请在 n8n 中重新选择对应凭证"
        }
      }
    },
    {
      "parameters": {
        "modelId": {
          "__rl": true,
          "mode": "id",
          "value": "gpt-5.6-terra"
        },
        "responses": {
          "values": [
            {
              "content": "={{ '请读取上一个 WordPress API 节点返回的最新一篇文章。提取正文并去除 HTML 标签、短代码和无关导航,只输出一段 180 至 300 字的中文内容摘要。摘要必须覆盖文章主题、关键事实与主要结论;不要输出标题、链接、封面、Markdown、JSON、代码围栏或额外说明。目标博客:https://hfz.pw。文章数据:\\n' + JSON.stringify($json) }}"
            }
          ]
        },
        "builtInTools": {},
        "options": {
          "maxTokens": 1200,
          "store": false
        }
      },
      "id": "summarize-wordpress-post",
      "name": "AI 模型智能体(提取并总结最新文章)",
      "type": "@n8n/n8n-nodes-langchain.openAi",
      "typeVersion": 2.3,
      "position": [
        688,
        320
      ],
      "retryOnFail": true,
      "maxTries": 3,
      "waitBetweenTries": 5000,
      "credentials": {
        "openAiApi": {
          "id": "REPLACE_WITH_OPENAIAPI_CREDENTIAL_ID",
          "name": "请在 n8n 中重新选择对应凭证"
        }
      }
    },
    {
      "parameters": {
        "dataTableId": {
          "__rl": true,
          "value": "REPLACE_WITH_WPMD_TABLE_ID",
          "mode": "list",
          "cachedResultName": "wpmd"
        },
        "columns": {
          "mappingMode": "defineBelow",
          "value": {
            "title": "={{ $('博客网址与应用密钥').item.json.title?.rendered || $('博客网址与应用密钥').item.json.title || '' }}",
            "summary": "={{ $json.output?.find(item => item.type === 'message')?.content?.find(item => item.type === 'output_text')?.text || '' }}",
            "link": "={{ $('博客网址与应用密钥').item.json.link || '' }}",
            "cover_image": "={{ $('博客网址与应用密钥').item.json._embedded?.['wp:featuredmedia']?.[0]?.source_url || '' }}"
          },
          "matchingColumns": [],
          "schema": [
            {
              "id": "title",
              "displayName": "title",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "summary",
              "displayName": "summary",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "link",
              "displayName": "link",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            },
            {
              "id": "cover_image",
              "displayName": "cover_image",
              "required": false,
              "defaultMatch": false,
              "display": true,
              "type": "string",
              "readOnly": false,
              "removed": false
            }
          ],
          "attemptToConvertTypes": false,
          "convertFieldsToString": false
        },
        "options": {}
      },
      "id": "save-wordpress-post",
      "name": "保存最新文章到 wpmd",
      "type": "n8n-nodes-base.dataTable",
      "typeVersion": 1.1,
      "position": [
        1008,
        320
      ]
    }
  ],
  "connections": {
    "手动触发": {
      "main": [
        [
          {
            "node": "博客网址与应用密钥",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "每日 07:30": {
      "main": [
        []
      ]
    },
    "博客网址与应用密钥": {
      "main": [
        [
          {
            "node": "AI 模型智能体(提取并总结最新文章)",
            "type": "main",
            "index": 0
          }
        ]
      ]
    },
    "AI 模型智能体(提取并总结最新文章)": {
      "main": [
        [
          {
            "node": "保存最新文章到 wpmd",
            "type": "main",
            "index": 0
          }
        ]
      ]
    }
  },
  "settings": {
    "executionOrder": "v1",
    "callerPolicy": "workflowsFromSameOwner",
    "binaryMode": "separate",
    "timeSavedMode": "fixed",
    "availableInMCP": true
  },
  "active": false,
  "pinData": {},
  "tags": []
}
Data Table Schema:horizon_summaries、content_articles、wpmd(点击展开代码)
{
  "export_type": "n8n_data_table_schema",
  "schema_version": 1,
  "generated_from": "current published n8n instance",
  "includes_rows": false,
  "instructions": [
    "在 n8n 的 Data Tables 页面按 name 创建数据表。",
    "严格按照 columns 顺序创建字段,所有字段类型均为 string。",
    "创建完成后,在工作流节点中重新选择对应 Data Table。",
    "不要直接使用示例中的 REPLACE_WITH_*_TABLE_ID 占位符。"
  ],
  "tables": [
    {
      "name": "horizon_summaries",
      "purpose": "保存每天联网采集的 AI 新闻摘要",
      "table_id_placeholder": "REPLACE_WITH_HORIZON_SUMMARIES_TABLE_ID",
      "columns": [
        {
          "index": 0,
          "name": "run_id",
          "type": "string"
        },
        {
          "index": 1,
          "name": "status",
          "type": "string"
        },
        {
          "index": 2,
          "name": "summary_date",
          "type": "string"
        },
        {
          "index": 3,
          "name": "summary_file_name",
          "type": "string"
        },
        {
          "index": 4,
          "name": "summary_markdown",
          "type": "string"
        },
        {
          "index": 5,
          "name": "error",
          "type": "string"
        }
      ]
    },
    {
      "name": "content_articles",
      "purpose": "保存生成的文章、封面路径和微信草稿状态",
      "table_id_placeholder": "REPLACE_WITH_CONTENT_ARTICLES_TABLE_ID",
      "columns": [
        {
          "index": 0,
          "name": "article_key",
          "type": "string"
        },
        {
          "index": 1,
          "name": "source_run_id",
          "type": "string"
        },
        {
          "index": 2,
          "name": "summary_date",
          "type": "string"
        },
        {
          "index": 3,
          "name": "title",
          "type": "string"
        },
        {
          "index": 4,
          "name": "markdown",
          "type": "string"
        },
        {
          "index": 5,
          "name": "article_status",
          "type": "string"
        },
        {
          "index": 6,
          "name": "image_path",
          "type": "string"
        },
        {
          "index": 7,
          "name": "image_status",
          "type": "string"
        },
        {
          "index": 8,
          "name": "wechat_status",
          "type": "string"
        },
        {
          "index": 9,
          "name": "wechat_media_id",
          "type": "string"
        },
        {
          "index": 10,
          "name": "error",
          "type": "string"
        }
      ]
    },
    {
      "name": "wpmd",
      "purpose": "保存 WordPress 最新文章的标题、摘要、链接和封面",
      "table_id_placeholder": "REPLACE_WITH_WPMD_TABLE_ID",
      "columns": [
        {
          "index": 0,
          "name": "title",
          "type": "string"
        },
        {
          "index": 1,
          "name": "summary",
          "type": "string"
        },
        {
          "index": 2,
          "name": "link",
          "type": "string"
        },
        {
          "index": 3,
          "name": "cover_image",
          "type": "string"
        }
      ]
    }
  ]
}
暂无评论内容